Free Microsoft AI-300 Practice Test Questions MCQs

Stop wondering if you're ready. Our Microsoft AI-300 practice test is designed to identify your exact knowledge gaps. Validate your skills with Operationalizing Machine Learning and Generative AI Solutions (beta) questions that mirror the real exam's format and difficulty. Build a personalized study plan based on your free AI-300 exam questions mcqs performance, focusing your effort where it matters most.

Targeted practice like this helps candidates feel significantly more prepared for Operationalizing Machine Learning and Generative AI Solutions (beta) exam day.

2600+ already prepared
Updated On : 12-Oct-2026
60 Questions
Operationalizing Machine Learning and Generative AI Solutions (beta)
4.9/5.0

Page 1 out of 6 Pages

Topic 1: Fabrikam Inc.

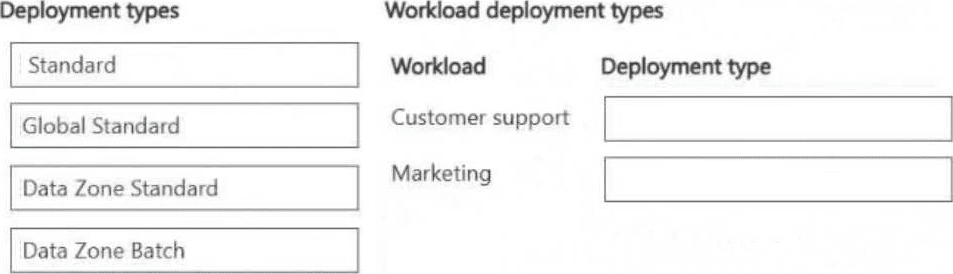
A company plans to deploy a foundation model in Microsoft Foundry.

The mode must support the following workloads:

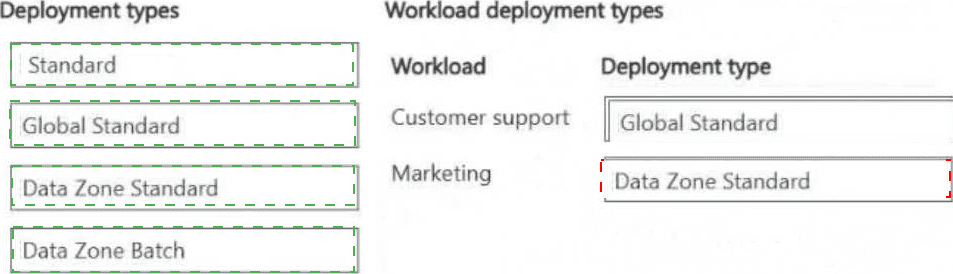
A customer support workload used across multiple regions

A marketing workload that must remain within a specific region due to data residency requirements You need to select the deployment type.

Which deployment type should you use for each workload? To answer, move the appropriate deployment types to the correct requirements. You may use each deployment type once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content. NOTE: Each correct selection is worth one point.

A Retrieval-Augmented Generation (RAG) solution returns incomplete answers because relevant content is inconsistently retrieved from the knowledge source.

You need to improve RAG accuracy without changing the embedding model currently in use. You need to achieve this goal while minimizing operational costs.

Which two actions should you perform? Each correct answer presents part of the solution.

NOTE: Each correct selection is worth one point. Choose two.

A. Tune chunk size and overlap to match content structure.

B. Implement an optimized re-ranker.

C. Increase token limits for all requests.

D. Optimize the length of embedding vectors.

A.   Tune chunk size and overlap to match content structure.
B.   Implement an optimized re-ranker.

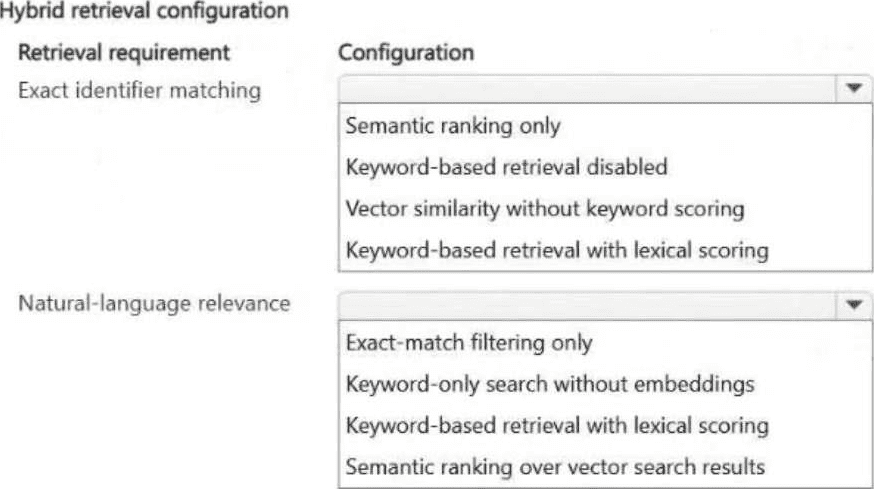
You manage a Retrieval-Augmented Generation (RAG) system that uses Azure AI Search to retrieve documents from an indexed knowledge base.

The system must support the following retrieval requirements:

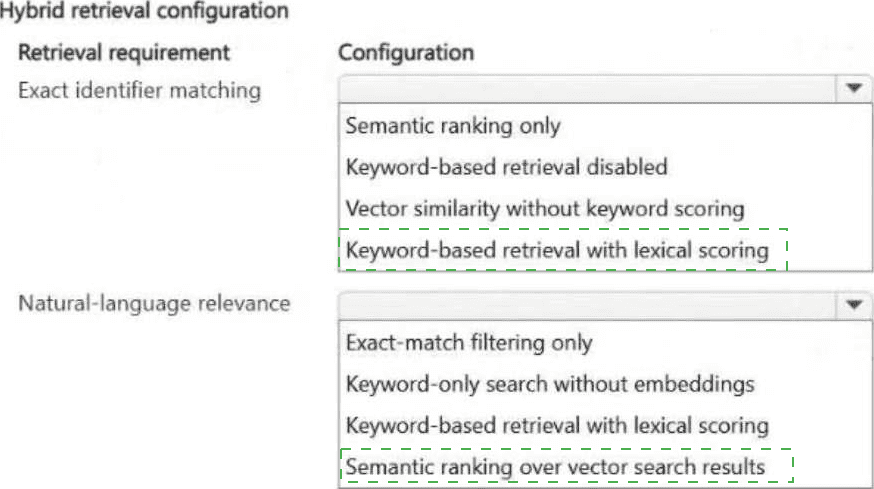
Queries that include exact policy identifiers must return matching documents even when semantic similarity is low.

Natural-language questions must prioritize semantically relevant documents even when keywords are not an exact match.

You need to configure the retrieval approach to meet the requirements.

How should you configure the retrieval behavior for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.

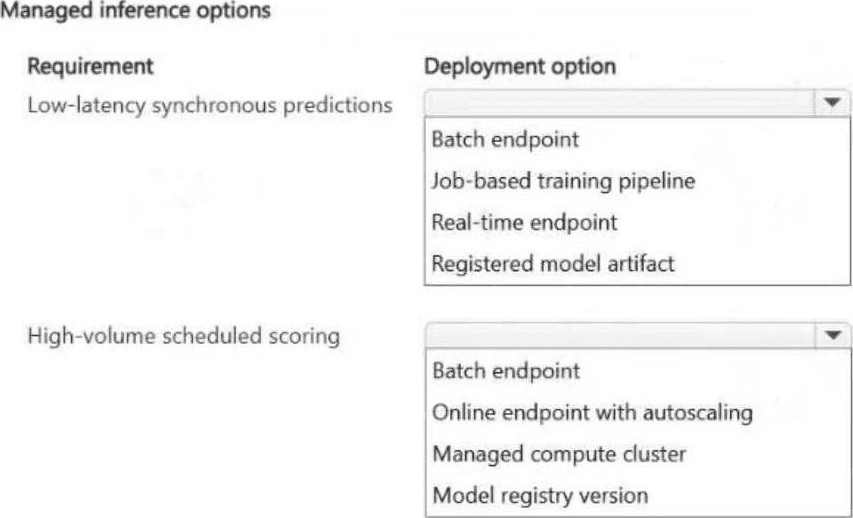
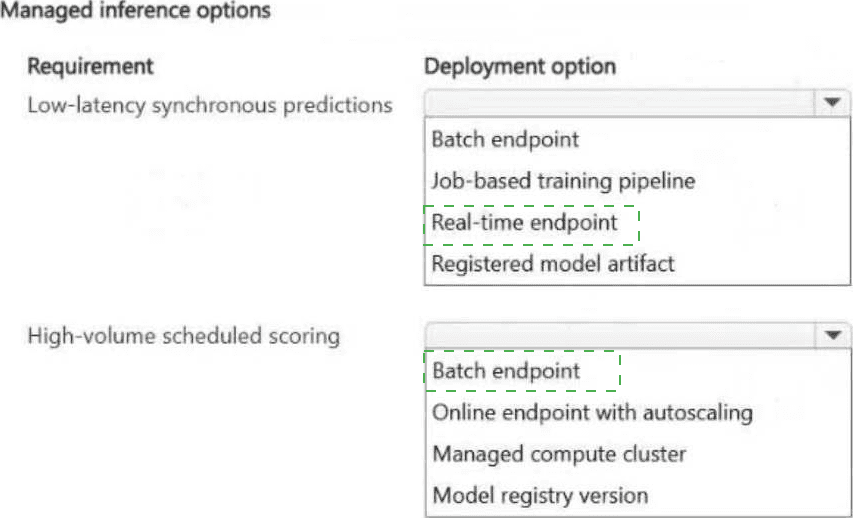
A team trains an MLflow model that scores customer churn risk. The model will be consumed by different downstream systems.

One system requests predictions synchronously during customer interactions.

Another system submits files containing millions of records for scheduled scoring.

You need to deploy the model by using managed inference options that match each usage pattern.

Which option should you use for each usage pattern? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.

Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.

After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.

You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data.

The training_data argument specifies the path to the training data in a file named dataset1.csv.

You plan to run the script.py Python script as a command job that trains a machine learning model.

You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.

Solution: python script.py dataset1.csv

Does the solution meet the goal?

A. Yes

B. No

B.   No

A team deploys a model to a real-time endpoint in Azure Machine Learning. You deploy some updates to the endpoint.

The endpoint returns errors after the new deployment is released.

You need to restore the service as quickly as possible.

What should you do first?

A. Roll back traffic to the previous deployment.

B. Delete the endpoint and immediately redeploy it.

C. Change the authentication type to Azure Machine Learning token-based authentication.

D. Increase the compute size.

A.   Roll back traffic to the previous deployment.

A team develops and manages a conversational assistant by using Microsoft Foundry.

The team must be able to validate that the assistant does not produce hateful responses before the application is exposed to any users.

You need to evaluate the model output for hateful responses as part of a repeatable validation process.

Which evaluator should you configure first?

A. Protected material

B. Groundedness

C. Indirect attacks

D. Content safety

D.   Content safety

Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.

After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.

You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data.

The training_data argument specifies the path to the training data in a file named dataset1.csv.

You plan to run the script.py Python script as a command job that trains a machine learning model.

You need to provide the command to pass the path for the dataset as a parameter value

when you submit the script as a training job.

Solution: python script.py --trainingdata ${{inputs.training_data}}

Does the solution meet the goal?

A. Yes

B. No

B.   No

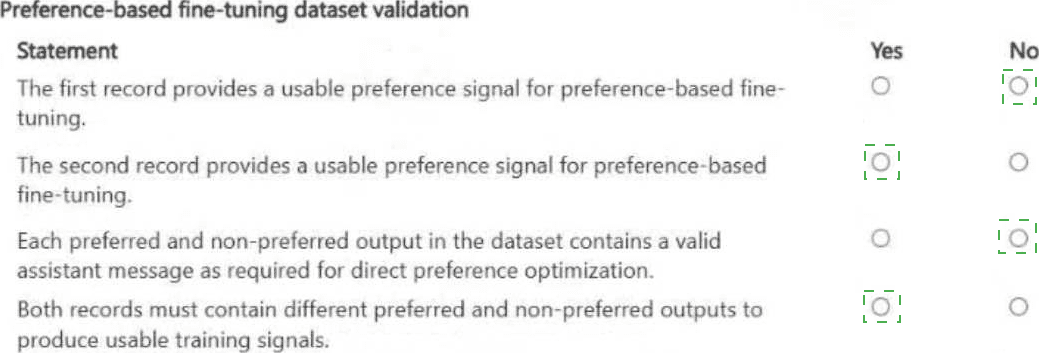
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.

The fine-tuning job uses preference comparison data.

You review the following dataset excerpt.
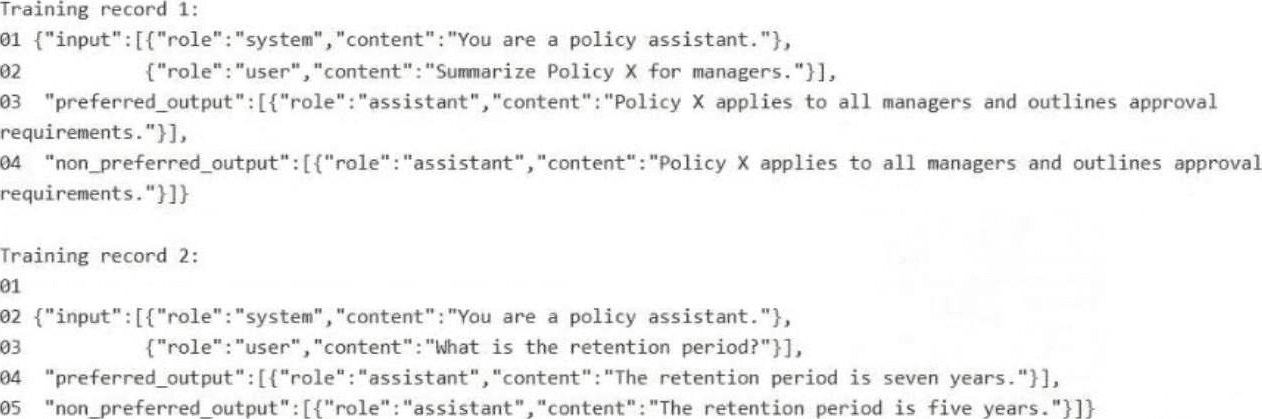


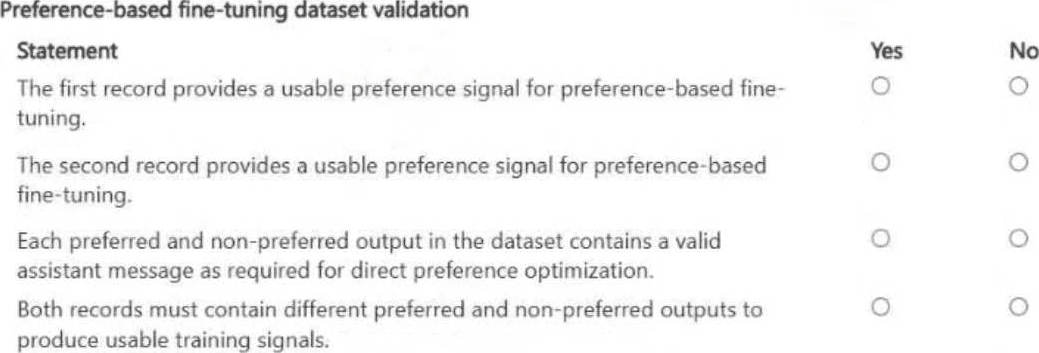
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.

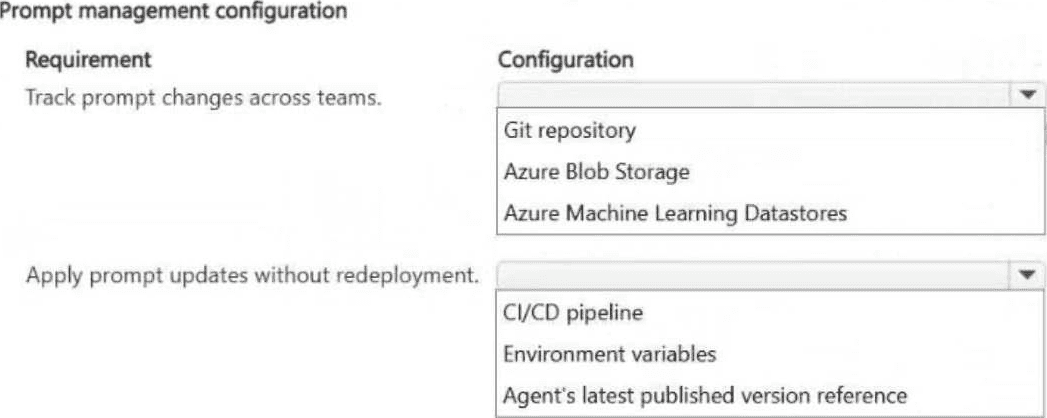
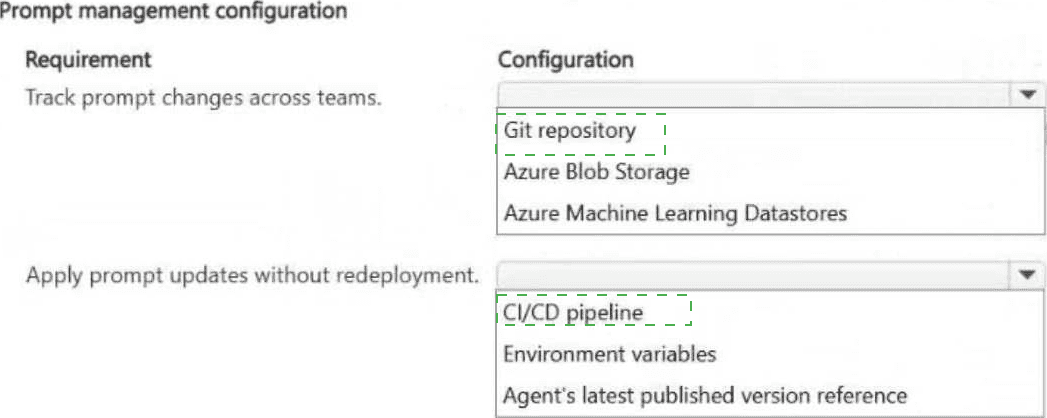
A team is building a generative AI agent by using Retrieval-Augmented Generation (RAG) in Microsoft Foundry.

The team frequently updates prompt content. The team must be able to track changes across contributors while avoiding full application redeployments.

You need to enable rapid prompt iteration with traceability. Applications consuming the agent must be able to use updated prompts without requiring redeployment.

What should you configure for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.

Page 1 out of 6 Pages
12

Operationalizing Machine Learning and Generative AI Solutions (beta) Practice Exam Questions